
OVHcloud Opens Olala Mini, Its First LLM
OVHcloud on Nov. 17, 2026, announced Olala mini 7A1B, its first in-house LLM: a 7B-parameter mixture-of-experts model with 1B active parameters, trained on Jupiter, MeluXina and Jean Zay and due on Hugging Face under Apache 2.0 at its Nov. 19 AI Summit.
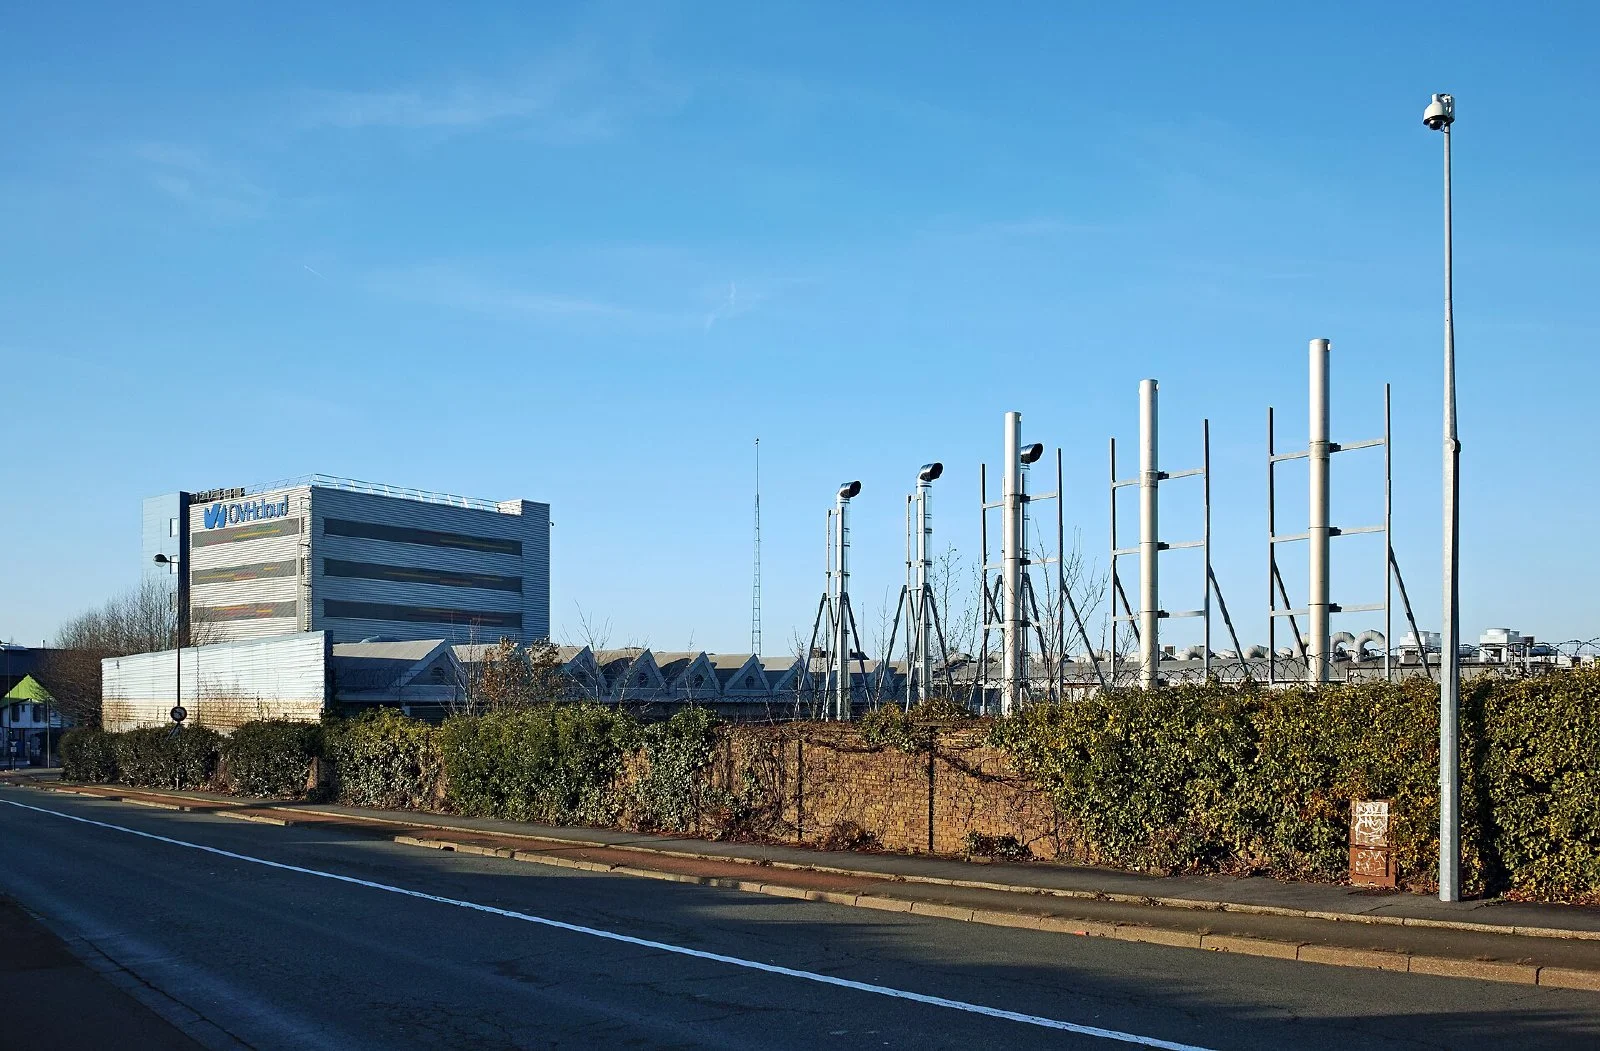
French cloud provider OVHcloud on Tuesday, Nov. 17, announced Olala, its first family of large language models, led by a compact open model called Olala mini 7A1B. The company says the model was trained from scratch on three European public supercomputers and will be released on Hugging Face under the Apache 2.0 license, with a formal launch set for its AI Summit on Nov. 19.
Key takeaways
- Olala mini 7A1B has 7 billion parameters, of which 1 billion are active per request, spread across 256 experts per layer.
- OVHcloud says it runs on a GPU with as little as 8GB of memory, at 160 tokens per second on an Nvidia RTX A4500 and 50 tokens per second on a standard CPU.
- The announcement includes speed figures and one customer, search engine Qwant, but no published quality benchmarks yet.
What is Olala mini 7A1B?
The name describes the design: 7 billion total parameters, 1 billion active. According to OVHcloud's press release, the mixture-of-experts model uses a hybrid attention scheme that combines Differential-TPA and Mamba-3, and ships in BF16 format. Only a fraction of the network runs for each request, which the company says makes it faster and less memory-hungry.
The current context window is 32,000 tokens. OVHcloud says the release will include the model weights, the pre-trained base model, a technical report and documentation for compliance with the EU AI Act.
| Item | Figure |
|---|---|
| Total / active parameters | 7 billion / 1 billion |
| Experts per layer | 256 |
| Context window | 32,000 tokens (128,000 planned in v1.1) |
| Speed, Nvidia RTX A4500 | 160 tokens/s |
| Speed, standard CPU | 50 tokens/s |
| Minimum GPU memory | 8GB |
| License | Apache 2.0 |
Trained on Europe's public supercomputers
OVHcloud trained the model on Jupiter in Germany, MeluXina in Luxembourg and Jean Zay in France, using Nvidia GH200, A100 and H100 GPUs. The company values that public support at the equivalent of €7 million in computing hours and says the effort gave rise to its agentic lab, OVHai LLM.
That lab grew out of Dragon LLM, formerly Lingua Custodia, a Paris company whose acquisition OVHcloud announced on March 25, 2026, French AI outlet ActuIA reported.
"We cannot simply rely on the generosity of certain labs to share their LLMs as open source in the years to come," CEO Octave Klaba said in the release. He added that "the cost of training has been divided by 20 in three years."
Qwant is the first user
Qwant already uses Olala mini for its flash answer feature. OVHcloud says answers arrive 20% faster and running costs are divided by three compared with the model used before, which it did not name.
Those results come from the company itself. ActuIA noted that Qwant is controlled by Octave and Miroslaw Klaba through holding company Synfonium, and that the announcement contained no evaluation scores. It also pointed out that 7 billion BF16 parameters take about 14GB, so the 8GB figure likely depends on compression or partial loading of experts, which OVHcloud has not detailed.
Context: Europe's push for its own models
The release lands as European companies and governments try to reduce dependence on U.S. technology providers. France's Mistral AI is the region's best-known model maker and raised €3 billion in September. OVHcloud, which says it runs 46 data centers and serves 1.7 million customers in more than 140 countries, is now adding its own models to its cloud business.
What's next for Olala
Version 1.1, due by the end of the year, will extend the context window to 128,000 tokens and improve mathematical reasoning, OVHcloud says. Olala v2.0 will exceed 100 billion parameters and target three areas: enterprise agentic AI, including an encrypted OVHai Workspace that needs models running locally on a workstation; cloud DevOps; and cybersecurity.
The technical report expected with the Nov. 19 release should be the first chance to compare Olala mini's answer quality with other small open models.
FAQ
When can developers download Olala mini?
OVHcloud says the model will be available on Hugging Face under Apache 2.0, with its official launch at the OVHcloud AI Summit on Nov. 19.
Can Olala mini run without a GPU?
Yes, according to OVHcloud, which reports 50 tokens per second on a standard processor without naming the chip.
Has its quality been benchmarked?
Not publicly. The announcement gives speed and cost figures only; a technical report is due with the release.
References
- OVH announces Olala mini 7A1B — OVHcloud (Nov. 17, 2026)
- OVHcloud unveils Olala mini, its first LLM: speeds, no scores — ActuIA (Nov. 17, 2026)
- OVHcloud launches European-trained open source AI model — ITPro (Nov. 17, 2026)
Editor responsible for AI Newsway. Writes about AI, developer tools, cloud and productivity technology.

Comments 0
Comments are currently disabled.