
Nvidia GR00T 2 Robots Hit 95% With 5 Demos
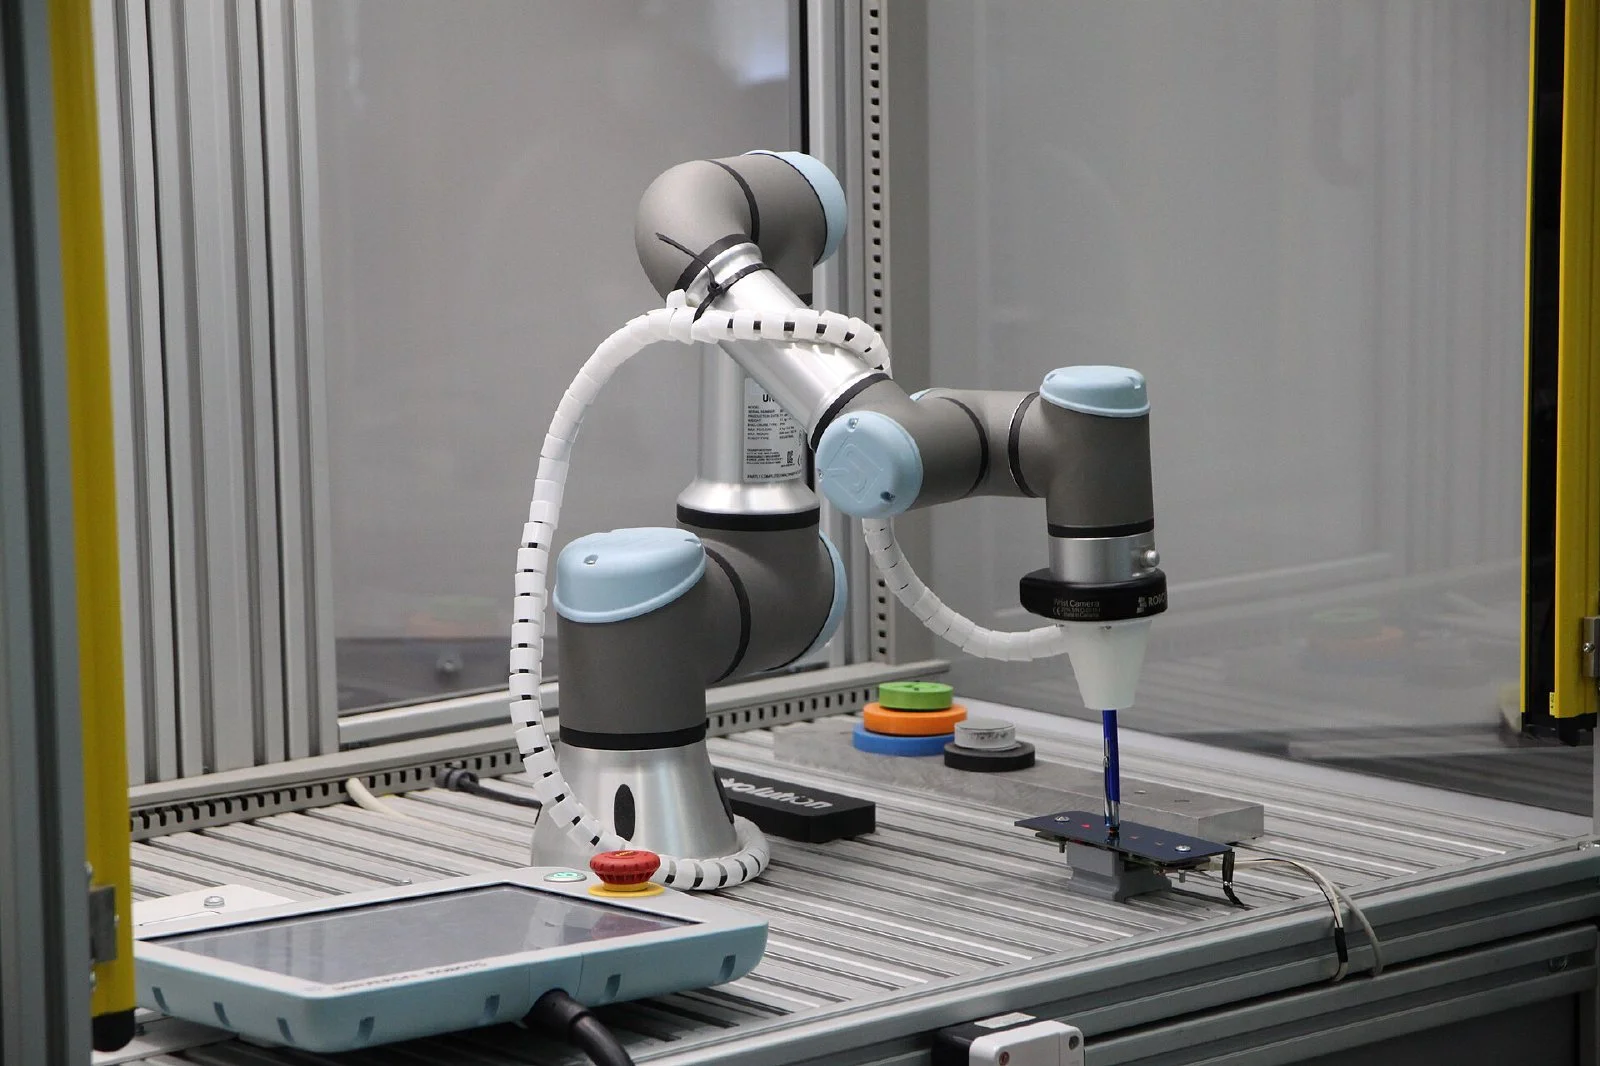
Nvidia on Nov. 9 introduced GR00T 2, an open world action model for robots, at CoRL in Austin. On 50 tasks the target robot had never practiced, it reached 40% success zero-shot, 71% with one demonstration per task and 95% with five, Nvidia said. The company also released Isaac Lab 3.0 and the DexBench and VABAR benchmarks.
Nvidia on Nov. 9 introduced GR00T 2, an open "world action model" for robots that learns largely from video of people working, at the Conference on Robot Learning (CoRL) in Austin, Texas. In Nvidia's tests on 50 tasks the target robot had never practiced, the model reached 71% average success with a single demonstration per task and 95% with five.
Key takeaways
- GR00T 2 predicts future video and robot actions together, which lets it pick up physics from human footage rather than only from robot teleoperation.
- On 50 unseen tasks, success rose from 40% zero-shot to 71% with one demo and 95% with five, each after a 30-minute fine-tune on one RTX 5090 GPU.
- Nvidia also shipped Isaac Lab 3.0, which it says delivers up to 2.5 times the training throughput of version 2.3 on a dexterous-manipulation benchmark. All figures are Nvidia's own.
What is Nvidia GR00T 2?
GR00T 2 is built on Nvidia's Cosmos world models. A single diffusion transformer reads recent camera frames, an instruction and the robot's state, then generates both the next few moments of video and a chunk of motor commands. Small per-robot "heads" adapt that plan to each body.
According to Nvidia's GEAR lab project page, pretraining mixed 402,730 hours of first-person video of people at work, 10,184 hours of demonstrations recorded with a handheld gripper across 2,897 tasks, and 23,500 hours of robot teleoperation. Nvidia has released 100,000 hours of the human video on Hugging Face as Human-1M-100K.
GR00T 2 results: zero-shot to five demos
The headline test used a two-armed robot with Sharpa hands on 50 tasks that appeared only in human video or other robots' data. Zero-shot, the model succeeded in 40% of trials and completed 40 of the 50 tasks at least once.
Five demonstrations, under three minutes of robot data per task, lifted average success to 95%, with 37 tasks succeeding in every trial.
Paired with a reasoning agent that calls it through an API, GR00T 2 assembled a toy plane, tractor and Hot Wheels car in 292 of 300 trials. A smaller 2-billion-parameter variant, GR00T 2 Turbo, runs on a Unitree G1 humanoid's onboard Jetson Thor at 124 milliseconds per prediction.
Isaac Lab 3.0 and new robot benchmarks
Nvidia's CoRL announcement paired the model with Isaac Lab 3.0, its open-source robot-learning framework, now tied more closely to the Newton physics engine. It also introduced two open benchmarks: DexBench, built with RLWRLD, with 15 tasks across four scenes, and VABAR, built with UC Berkeley, covering six industrial tasks.
Nvidia said Foxconn is applying GR00T 2 to server manufacturing, Siemens is evaluating it, and Nexuni is testing it for laundry handling.
Context: robotics' data problem
Robots lack the internet-scale data that trained chatbots. UC Berkeley roboticist Ken Goldberg has described a "100,000-year data gap." GR00T 2 attacks that by mining human video, while Goldberg's "agentic robotics" work, presented at the same conference, uses AI agents to write and rehearse robot programs in simulation.
"Agentic robotics is a fundamental shift in how robots are controlled," Goldberg said in a Berkeley News article. General models are also being tested on hardware, as in our report on how GPT-6 Astra finished a real cone course at 0.94 mph.
What's next
Nvidia's project page reports its own limits: with visual steering, the Dexter robot rarely completes full long-horizon trash sorting. Independent groups have yet to reproduce the results, and the announcement did not give a release date for GR00T 2 weights. The DexBench and VABAR leaderboards should offer the first outside comparisons.
FAQ
What is a world action model?
It is a robot model that predicts how a scene will change along with the actions to take. GR00T 2 generates future video and motor commands together, rather than outputting actions alone.
Can GR00T 2 learn a task without robot demonstrations?
In some cases. Nvidia says a robot with two five-fingered hands lined a lab funnel with filter paper in 65% of trials after seeing the task only in human demonstrations.
References
- GR00T 2: Scaling Robot Foundation Models for Generalization, Dexterity, and Adaptation — NVIDIA GEAR (Nov. 2026)
- Practice Makes Precise: At CoRL, NVIDIA and Partners Reveal How Robots Rehearse Delicate Work in Simulation — NVIDIA Blog (Nov. 9, 2026)
- Recent advances in AI are creating a 'paradigm shift' for robotics — Berkeley News (Nov. 9, 2026)
Editor responsible for AI Newsway. Writes about AI, developer tools, cloud and productivity technology.

Comments 0
Comments are currently disabled.