
Patch Squeezes 284B DeepSeek Into 64GB RAM
Open-source project llama-modchip says v2.4.0 runs the 284-billion-parameter DeepSeek-V4-Flash on a 64GB PC with no GPU at 9.06 to 9.95 tokens per second, by its own measurements.
An open-source project called llama-modchip says its Nov. 4 release can run DeepSeek-V4-Flash, a model with 284 billion parameters, on an ordinary 64GB PC with no graphics card. The project, published by the GitHub account synchopate, drew 355 points on Hacker News after it was posted Nov. 8. The catch: the speed figures for the big model are the project's own, and the answer arrives at roughly 10 tokens per second.
- Version 2.4.0 cuts a compressed DeepSeek-V4-Flash build from 76.87 GiB to 56.56 GiB, small enough to stay in 64GB of memory with no swap, according to the project.
- On a 16-core AMD Ryzen 9 9955HX with no GPU, the project reports 9.06 to 9.95 tokens per second of generation at 256K context.
- The "lossless" label compares the patched and unpatched software on the same shrunken file, not against DeepSeek's original weights.
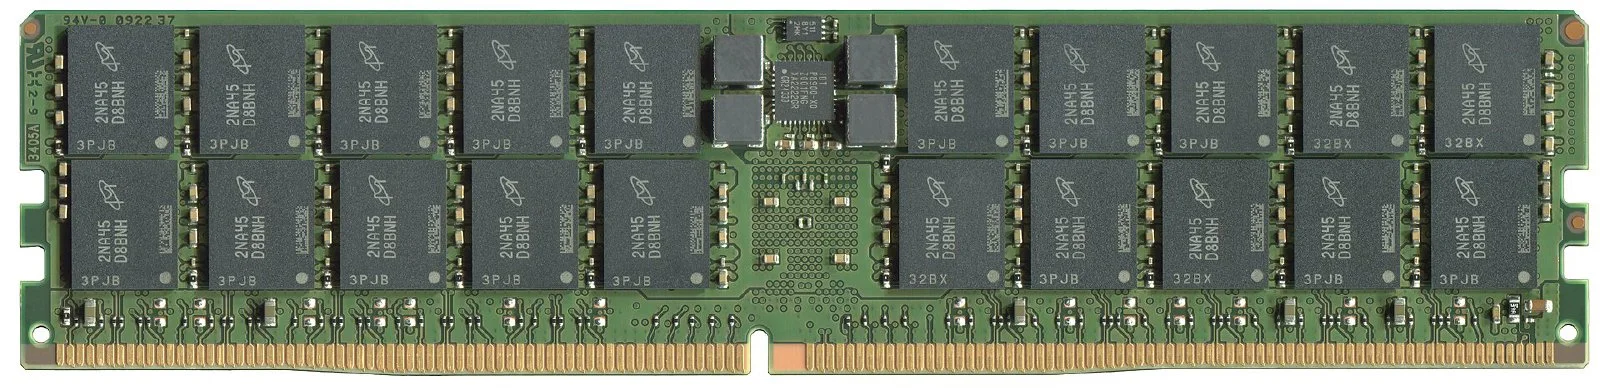
How llama-modchip fits DeepSeek in 64GB
DeepSeek's model card lists V4-Flash at 284 billion total parameters, of which 13 billion are active per token.
The model card for the new build says a standard 76.87 GiB community quantization overflows the roughly 62.5 GiB that a 64GB Linux machine can use. Llama-modchip starts from that Unsloth file and compresses further, keeping most routed experts at about 1.56 bits per weight.
| Metric | Standard build | llama-modchip v2.4.0 |
|---|---|---|
| File size | 76.87 GiB | 56.56 GiB |
| Memory at 256K context | Over 64 GiB | 57.61–58.9 GiB |
| Prompt ingestion | 25.0 tok/s | 43.16–44.36 tok/s |
| Generation | 5.91 tok/s | 9.06–9.95 tok/s |
The gains come from CPU-specific patches to llama.cpp, the release notes say. The starting point varies by document: the README gives 5.91 tokens per second, while the model card gives 6.41. At 9.06 tokens per second, a 500-token reply would take about 55 seconds.
What "lossless" does and does not mean
The project reports a logit cosine similarity of 1.00000 and calls its default mode bit-exact. Its README states that this is measured against the unpatched runtime on the same 56.56 GiB checkpoint. That shows the speed patches do not change the output of the compressed file. It says nothing about how much quality the compression itself removed compared with DeepSeek's weights, which use FP4 for experts and FP8 for most other parameters.
The pages AI Newsway reviewed publish a 100-point quality score for a 30-billion-parameter Nemotron build, but no equivalent for the 284B file. AI Newsway did not run the software.
Why it matters for local LLM users
Running large open models locally has mostly meant expensive unified-memory machines or GPUs. A reference table for antirez's ds4 engine, which AI Newsway covered in October, showed 34.4 tokens per second on a 128GB M5 Max at 32,768-token context. Llama-modchip trades that speed for cheaper hardware. It also runs below the model's native 1 million-token context.
The files need the project's own engine. Unpatched llama.cpp, Ollama and LM Studio reject them with an unknown tensor type error, the README says. The build is also based on the 0731 checkpoint, and DeepSeek has since moved on to V4.1 Flash.
What's next
The repository's issue tracker filled with benchmark submissions on Nov. 8, and the project has added 17 commits since v2.4.0. The third-party results its FAQ cites concern the smaller Nemotron model, so independent runs of the 284B build and a published quality benchmark are the next things to watch.
FAQ
Can llama-modchip run DeepSeek-V4-Flash on 32GB of RAM?
Not the 284B build, which needs 57.61 to 58.9 GiB. For 16GB to 32GB machines, the project points to a 14.35 GiB build of Nvidia's 30-billion-parameter Nemotron 3.5.
Is llama-modchip open source?
Yes. The repository is labeled Apache 2.0.
References
- GitHub - synchopate/llama-modchip — GitHub
- Release v2.4.0 · synchopate/llama-modchip — GitHub (Nov. 4, 2026)
- llama-modchip/FAQ.md — GitHub
- Synchopate/DeepSeek-V4-Flash-0731-Fractal-64GB-CPU-GGUF — Hugging Face
- deepseek-ai/DeepSeek-V4-Flash — Hugging Face
- Llama-modchip: 284B DeepSeek on 64GB RAM, no GPU — Hacker News (Nov. 8, 2026)
Editor responsible for AI Newsway. Writes about AI, developer tools, cloud and productivity technology.

Comments 0
Comments are currently disabled.