Mercury 2.5 Ships at 1,107 Tokens a Second and Four Cents a Million
A phone agent startup says Mercury cut its worst-case response from minutes to one second. Inception Labs' new diffusion model is built around that kind of number.
Seung Jung·
5mA phone agent startup says Mercury cut its worst-case response from minutes to one second. Inception Labs' new diffusion model is built around that kind of number.

Antitrust enforcers have opened their first real examination of the deal structure that has replaced the acquisition in AI: Nvidia has received a formal Justice...

DeepSeek V4.1 Flash needs 567GB of GPU memory rather than 763GB because 196 billion of its weights are built to run from system RAM instead.

AI-generated kernels beat OpenAI expert-written versions by up to 1.8x, as Jalapeño posts its first InferenceX benchmark results.
Nvidia's Groq 3 LPX rack is in full production, commercializing its largest-ever acquisition and targeting the decode latency that slows AI agents.
Etched raised $700M at a $21B valuation led by Jane Street, doubling its July price. The startup splits inference into prefill and decode with separate silicon.
Cerebras says its new CS-4 rack, built from three WSE-3 Turbo wafers, delivers 750 PFLOPS and up to 30x GPU per-user token speed. Shipments start this quarter.
NVIDIA released Nemotron 3.5 Lightning, a 30B open MoE model for agentic workloads, alongside NeMo Switchyard, an open source model-routing library.
OpenAI's new Ultrafast tier runs GPT-5.6 Sol at up to 750 tokens per second, 14x standard speed, powered by Cerebras wafer-scale chips in limited preview.
Meta's Muse Glimmer is a 30B open-weight agent model under Apache 2.0 that runs on one consumer GPU — its first open release in over a year.
Anthropic confirmed an in-house silicon team to co-design chips with Claude models, targeting roughly 50% lower cost per token as inference bills mount.
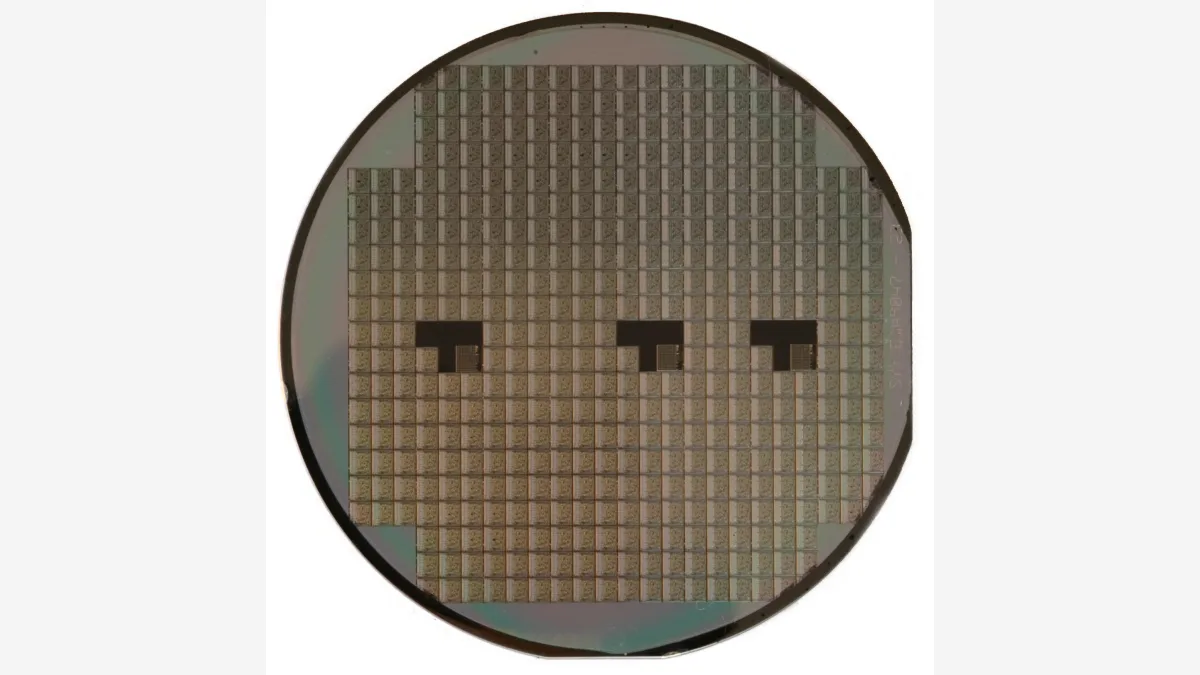
AMD is acquiring Toronto startup Taalas, whose chips etch AI model weights directly into silicon to sidestep the memory bottleneck in inference.