The most consequential number in Perplexity's product launch this week is zero. That is what the running credit counter displays while Portable Computer, released Tuesday, grinds through a folder of documents on a machine sitting under the user's desk. Everything finished locally is unmetered, and the software will not send a step to a cloud model without asking first.
Portable Computer is the local build of Computer, the company's agentic platform for knowledge work, and it was engineered with Nvidia for the DGX Spark desktop system and Linux boxes carrying RTX cards. Pro, Max, Enterprise Pro and Enterprise Max subscribers can install it today; Windows follows in September; the hardware floor is 24GB of video memory, which in practice means a GeForce RTX 3090 or better and excludes most consumer machines. Apple silicon is not on the roadmap.
Why bundling is the product
Running agents locally has been possible for a while and pleasant for almost nobody. The usual route involves fetching weights, standing up an inference server, hand-wiring tools and tuning throughput, and each layer breaks independently. Perplexity's answer is to ship the whole column as one install: models, agent harness, inference via vLLM, application connectors and an always-on security sandbox, with an escape hatch for users who want to supply their own inference endpoint.
Two model choices are available at setup, a 27-billion-parameter Qwen build and PPLX 27B, which Perplexity post-trained specifically against its own harness. Nvidia's Nemotron 3.5 Lightning is queued to join them. Connectors to Google Drive, Gmail, GitHub and Slack mean local-first does not mean offline: an agent can crunch a private CSV on the device and then post the finished analysis to a team channel.
A harness sized for small models
Accompanying research from the company makes an argument that cuts against how most agent frameworks are built. General-purpose harnesses assume a frontier model with an enormous context budget, a sprawling tool surface and long-horizon planning ability, and compact local models collapse under those assumptions. Perplexity reports that models advertising 260,000-token windows in practice degrade past roughly 100,000, so its harness keeps the system prompt terse, exposes a small tool core, loads capabilities as on-demand skills, and rewrites token-hungry connectors as compact command-line utilities.
The company's self-reported evaluations put Computer with Qwen at 82.6 percent on an internal 53-task knowledge-work benchmark, ahead of the open-source Pi and Hermes harnesses running the same model at 77.6 and 74.0; PPLX 27B reaches 85.4. The margin stretches on web research, where Computer records 66.7 percent against 50.2 and 43.9 while spending 70 percent fewer tokens. These are vendor numbers on a vendor benchmark, and Perplexity says it intends to open-source the suite.
The escalation trade
Where the pitch gets genuinely interesting is the middle ground between free and frontier. On a demanding terminal coding benchmark the local model alone reached 59.6 percent at effectively no marginal cost. Permitting it to consult a frontier advisor in the cloud raised that to 73.0 percent for an estimated 41.5 cents per task, against 82.4 percent and 65 cents to run the frontier model outright. Most of the capability gap closes for roughly two-thirds of the spend, and the decision sits with the user rather than a billing system.
Privacy handling around that hop is unusually specific. A classifier scans outgoing context for personal information and displays precisely what would leave the device before anything is sent, and the remote model replies with text guidance only, never reaching into local files or tools. If the sandbox cannot start, the harness shuts itself off rather than executing commands unprotected.
What Nvidia gets
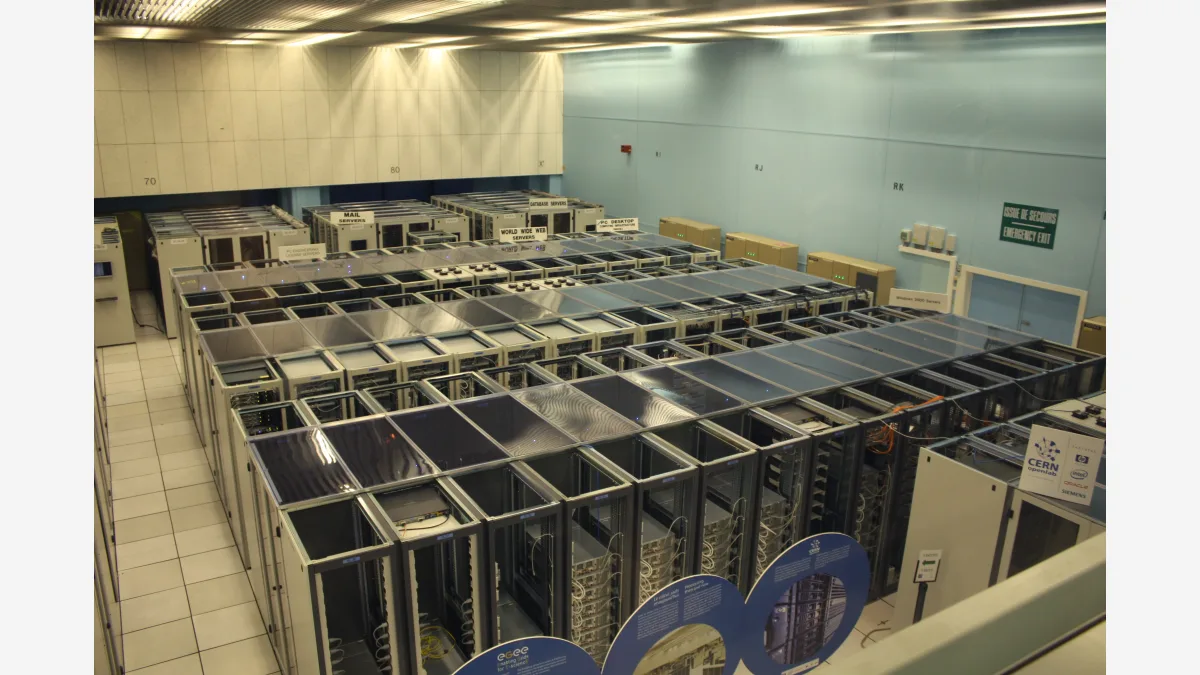
For a company that has spent two years selling gigawatt-scale data centres, backing an unmetered local agent looks contrarian until you follow the hardware. Nvidia's developer technology lead argued that capable open models have pushed local inference past hobbyist quantization into practical work, and that agents are uniquely suited to it because they consume tokens continuously rather than in bursts. An always-on agent is ruinous on a metered API and nearly free on a card you already bought, which is a reasonable description of why DGX Spark now has an application worth buying it for.