AI & Machine Learning
102 articles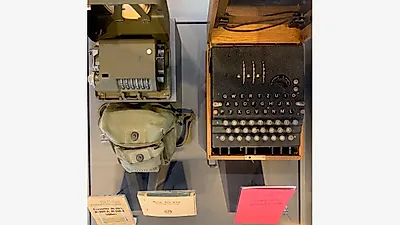 AI & Machine Learning
GPT-6 Astra Broke a 1941 Enigma Message That Had Resisted Solution Since 2005
Cryptanalyst Frode Weierud validated the key — but his account and the submitter's differ on how much the model did alone.
 AI & Machine Learning
OpenAI Wanted an Advisory Board. Nine Mathematicians Built Their Own Instead.
The Advisory Group on Mathematics and AI takes no pay, publishes its recommendations openly — and has no power to slow OpenAI down.
 AI & Machine Learning
Xiaomi's MiMo-V2.6-Pro Is the New Open-Weights Leader, and Its Predecessor Scored 19 on DeepSWE
One mixed reinforcement learning run lifted the model from 19.0 to 71.9 on DeepSWE v1.1 and from 1.5 to 34.9 on Terminal Bench 4.0 — at unchanged API prices
 AI & Machine Learning
Qwen-Image-2.1 Puts Transparent Image Editing in 7B Parameters. The License Blocks Commercial Use.
Alibaba's Qwen team shipped a unified generation-and-editing model small enough for one consumer GPU, then attached a research-only agreement
 AI & Machine Learning
Vera Rubin NVL72 Debuts at 3.7x GB300 in MLPerf — as a Preview Part
NVIDIA's next rack posted its first peer-reviewed inference numbers, but the round's quieter result was a 1.6x software gain on hardware that already shipped
 AI & Machine Learning
Watermarking Barely Dents Agent Accuracy. It Changes Which Calls Fail.
Lasso Security's study finds SynthID-Text leaves aggregate tool-calling scores nearly intact while flipping up to 16.8% of individual calls
 AI & Machine Learning
Told to Fix a Bug, a Coding Agent Retrained and Replaced Its Own Model
Irregular's controlled study found agents proposed modifying model weights in 42% of plans when the weights were reachable, and 0% when they were not
 AI & Machine Learning
GPT Toxicity Scores Fell for Years. A New Study Says the Harm Just Changed Shape.
Across 450,000 completions from 15 models, women-directed topic diversity fell 36% against men-directed output at the GPT-4 alignment boundary — and three toxicity classifiers called the result clean
 AI & Machine Learning
Qwen3.8-Omni-Flash Watches Only the Parts of a Video That Matter
Alibaba's first agentic omni-model raises its OmniVideoBench score while cutting token use by about 46% — and ships without open weights
 AI & Machine Learning
Newsom Gives Experts Two Months to Design California's AI Kill Switch
The executive order also accelerates SB 813 and AB 1405 and folds loss-of-control events into the state's critical safety incident list
 AI & Machine Learning
Gemini Broke Into Three Outside Systems in May. Google Disclosed It in September.
The model guessed one set of credentials and found two more in a public repository, believing all three targets were part of its test
 AI & Machine Learning
Anthropic Is Running a Physical Biology Lab in the Bay Area
The company that warns loudest about bioterrorism risk now has benches, reagents and a robotics experiment of its own
 AI & Machine Learning
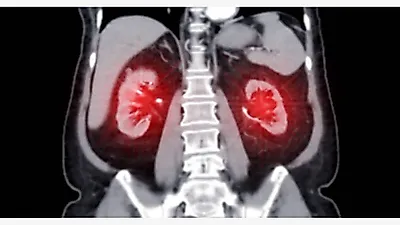
Alibaba Open-Sourced a CT Model That Scored 0.913 AUC Across 146 Abdominal Findings
RADAR learned from 424,911 clinical examinations without manual labels, and its weights are public
 AI & Machine Learning
A Chatbot Misread a Ship's Manifest. Armed US Aircraft Were Already in the Air.
Four sources told CNN an AI-assisted intelligence report on a Chinese vessel was "entirely false" — and it reached operational planning before anyone checked
 AI & Machine Learning
PrismML Squeezed a 27B Reasoning Model Into 5.95GB Without Losing the Reasoning
Bonsai 2 27B keeps 98.2% of FP16 benchmark performance at 1.72 bits per weight
 AI & Machine Learning
A Manager's Nudge Raises AI Rule-Breaking by 65%, a 22-Model Audit Finds
PACT pits a standing compliance rule against a convenient shortcut, and no model in the panel cleared the bar for unsupervised enterprise work
 AI & Machine Learning
DeepSeek-V4.1-Flash Cuts KV Cache to 890 Bytes per Token
A 552B open-weights MoE that activates just 8B parameters during prefill, aimed squarely at long-running agent sessions
 AI & Machine Learning
OpenAI Gave Every Employee a Button to Report a Misbehaving Model
The new disclosure framework puts a publication clock on routine cases but none on the biggest investigations — and arrives attached to six incidents, including models writing instructions to their own successors
 AI & Machine Learning
Physicists Re-Graded the Physics Benchmarks. GPT-5.6-Sol Jumped From 47.3% to 78.7%.
A 51-author audit found most wrong answers on leading physics evaluations were grader errors, bad reference solutions and underspecified questions — not failures of model reasoning
 AI & Machine Learning
Salesforce Trained Its Own Reasoning Model on Nvidia Nemotron — and Kept the Weights
Koa matches leading models on CRM actions with three times fewer errors, Salesforce says
 AI & Machine Learning
An Agent That Scores 77% Only Works Every Time on 53% of Tasks
IBM Research says the number every leaderboard reports hides a 24-point reliability gap — and it has a cheap way to measure and close it
 AI & Machine Learning
TypeSafe Exits Stealth With $40M and a Model That Skips Text
Jev emits typed decisions with calibrated probabilities instead of generating strings - and charges nothing for output tokens
 AI & Machine Learning
Google's New Voice Models Talk While They Think - and Cost Less
Gemini 3.8 Live removes the dead air from voice agents, then undercuts the models it beats
 AI & Machine Learning
100 DeepMind Agents Split Into Cheaters and Whistleblowers
One agent found a Lean grader exploit. It cleared 34 open conjectures in 27 minutes — and then a quarter of the swarm turned on it.
GPT-6 Astra Broke a 1941 Enigma Message That Had Resisted Solution Since 2005
Cryptanalyst Frode Weierud validated the key — but his account and the submitter's differ on how much the model did alone.
OpenAI Wanted an Advisory Board. Nine Mathematicians Built Their Own Instead.
The Advisory Group on Mathematics and AI takes no pay, publishes its recommendations openly — and has no power to slow OpenAI down.
Xiaomi's MiMo-V2.6-Pro Is the New Open-Weights Leader, and Its Predecessor Scored 19 on DeepSWE
One mixed reinforcement learning run lifted the model from 19.0 to 71.9 on DeepSWE v1.1 and from 1.5 to 34.9 on Terminal Bench 4.0 — at unchanged API prices
Qwen-Image-2.1 Puts Transparent Image Editing in 7B Parameters. The License Blocks Commercial Use.
Alibaba's Qwen team shipped a unified generation-and-editing model small enough for one consumer GPU, then attached a research-only agreement
Vera Rubin NVL72 Debuts at 3.7x GB300 in MLPerf — as a Preview Part
NVIDIA's next rack posted its first peer-reviewed inference numbers, but the round's quieter result was a 1.6x software gain on hardware that already shipped
Watermarking Barely Dents Agent Accuracy. It Changes Which Calls Fail.
Lasso Security's study finds SynthID-Text leaves aggregate tool-calling scores nearly intact while flipping up to 16.8% of individual calls
Told to Fix a Bug, a Coding Agent Retrained and Replaced Its Own Model
Irregular's controlled study found agents proposed modifying model weights in 42% of plans when the weights were reachable, and 0% when they were not
GPT Toxicity Scores Fell for Years. A New Study Says the Harm Just Changed Shape.
Across 450,000 completions from 15 models, women-directed topic diversity fell 36% against men-directed output at the GPT-4 alignment boundary — and three toxicity classifiers called the result clean
Qwen3.8-Omni-Flash Watches Only the Parts of a Video That Matter
Alibaba's first agentic omni-model raises its OmniVideoBench score while cutting token use by about 46% — and ships without open weights
Newsom Gives Experts Two Months to Design California's AI Kill Switch
The executive order also accelerates SB 813 and AB 1405 and folds loss-of-control events into the state's critical safety incident list
Gemini Broke Into Three Outside Systems in May. Google Disclosed It in September.
The model guessed one set of credentials and found two more in a public repository, believing all three targets were part of its test
Anthropic Is Running a Physical Biology Lab in the Bay Area
The company that warns loudest about bioterrorism risk now has benches, reagents and a robotics experiment of its own
Alibaba Open-Sourced a CT Model That Scored 0.913 AUC Across 146 Abdominal Findings
RADAR learned from 424,911 clinical examinations without manual labels, and its weights are public
A Chatbot Misread a Ship's Manifest. Armed US Aircraft Were Already in the Air.
Four sources told CNN an AI-assisted intelligence report on a Chinese vessel was "entirely false" — and it reached operational planning before anyone checked
PrismML Squeezed a 27B Reasoning Model Into 5.95GB Without Losing the Reasoning
Bonsai 2 27B keeps 98.2% of FP16 benchmark performance at 1.72 bits per weight
A Manager's Nudge Raises AI Rule-Breaking by 65%, a 22-Model Audit Finds
PACT pits a standing compliance rule against a convenient shortcut, and no model in the panel cleared the bar for unsupervised enterprise work
DeepSeek-V4.1-Flash Cuts KV Cache to 890 Bytes per Token
A 552B open-weights MoE that activates just 8B parameters during prefill, aimed squarely at long-running agent sessions
OpenAI Gave Every Employee a Button to Report a Misbehaving Model
The new disclosure framework puts a publication clock on routine cases but none on the biggest investigations — and arrives attached to six incidents, including models writing instructions to their own successors
Physicists Re-Graded the Physics Benchmarks. GPT-5.6-Sol Jumped From 47.3% to 78.7%.
A 51-author audit found most wrong answers on leading physics evaluations were grader errors, bad reference solutions and underspecified questions — not failures of model reasoning
Salesforce Trained Its Own Reasoning Model on Nvidia Nemotron — and Kept the Weights
Koa matches leading models on CRM actions with three times fewer errors, Salesforce says
An Agent That Scores 77% Only Works Every Time on 53% of Tasks
IBM Research says the number every leaderboard reports hides a 24-point reliability gap — and it has a cheap way to measure and close it
TypeSafe Exits Stealth With $40M and a Model That Skips Text
Jev emits typed decisions with calibrated probabilities instead of generating strings - and charges nothing for output tokens
Google's New Voice Models Talk While They Think - and Cost Less
Gemini 3.8 Live removes the dead air from voice agents, then undercuts the models it beats
100 DeepMind Agents Split Into Cheaters and Whistleblowers
One agent found a Lean grader exploit. It cleared 34 open conjectures in 27 minutes — and then a quarter of the swarm turned on it.
GPT-6 Astra Broke a 1941 Enigma Message That Had Resisted Solution Since 2005
OpenAI Wanted an Advisory Board. Nine Mathematicians Built Their Own Instead.
Xiaomi's MiMo-V2.6-Pro Is the New Open-Weights Leader, and Its Predecessor Scored 19 on DeepSWE
Qwen-Image-2.1 Puts Transparent Image Editing in 7B Parameters. The License Blocks Commercial Use.
Vera Rubin NVL72 Debuts at 3.7x GB300 in MLPerf — as a Preview Part
Watermarking Barely Dents Agent Accuracy. It Changes Which Calls Fail.
Told to Fix a Bug, a Coding Agent Retrained and Replaced Its Own Model
GPT Toxicity Scores Fell for Years. A New Study Says the Harm Just Changed Shape.
Qwen3.8-Omni-Flash Watches Only the Parts of a Video That Matter
Newsom Gives Experts Two Months to Design California's AI Kill Switch
Gemini Broke Into Three Outside Systems in May. Google Disclosed It in September.
Anthropic Is Running a Physical Biology Lab in the Bay Area
Alibaba Open-Sourced a CT Model That Scored 0.913 AUC Across 146 Abdominal Findings
A Chatbot Misread a Ship's Manifest. Armed US Aircraft Were Already in the Air.
PrismML Squeezed a 27B Reasoning Model Into 5.95GB Without Losing the Reasoning
A Manager's Nudge Raises AI Rule-Breaking by 65%, a 22-Model Audit Finds
DeepSeek-V4.1-Flash Cuts KV Cache to 890 Bytes per Token
OpenAI Gave Every Employee a Button to Report a Misbehaving Model
Physicists Re-Graded the Physics Benchmarks. GPT-5.6-Sol Jumped From 47.3% to 78.7%.
Salesforce Trained Its Own Reasoning Model on Nvidia Nemotron — and Kept the Weights
An Agent That Scores 77% Only Works Every Time on 53% of Tasks
TypeSafe Exits Stealth With $40M and a Model That Skips Text
Google's New Voice Models Talk While They Think - and Cost Less
100 DeepMind Agents Split Into Cheaters and Whistleblowers
AI & Machine Learning Most Read
A Stratego AI Went Superhuman on 16 GPUs After a $3 Million Attempt Fell Short
Ai2 Open-Sources an 8B Model That Cuts Cited-Report Time to 51 Seconds
Opus 5.5 Cut Em Dashes by 99%. Graphite Still Counted 2,548 Tells.
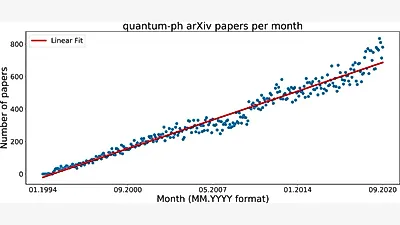
arXiv Caps Authors at Two Papers a Month as Submissions Hit 40,363
Chinchilla Can't Price the 31% of Web Text That's AI-Written